Research · Dataset release
OevuAI Image Training Corpus v1.0.0
A small, carefully built image–text dataset for studying training-data construction: every pair is documented, every release is checksummed, and the method behind it is written down.
79image–text pairs
298 MBtotal size
57 + 22dense-tag / structured bilingual pairs
SHA-256published per release
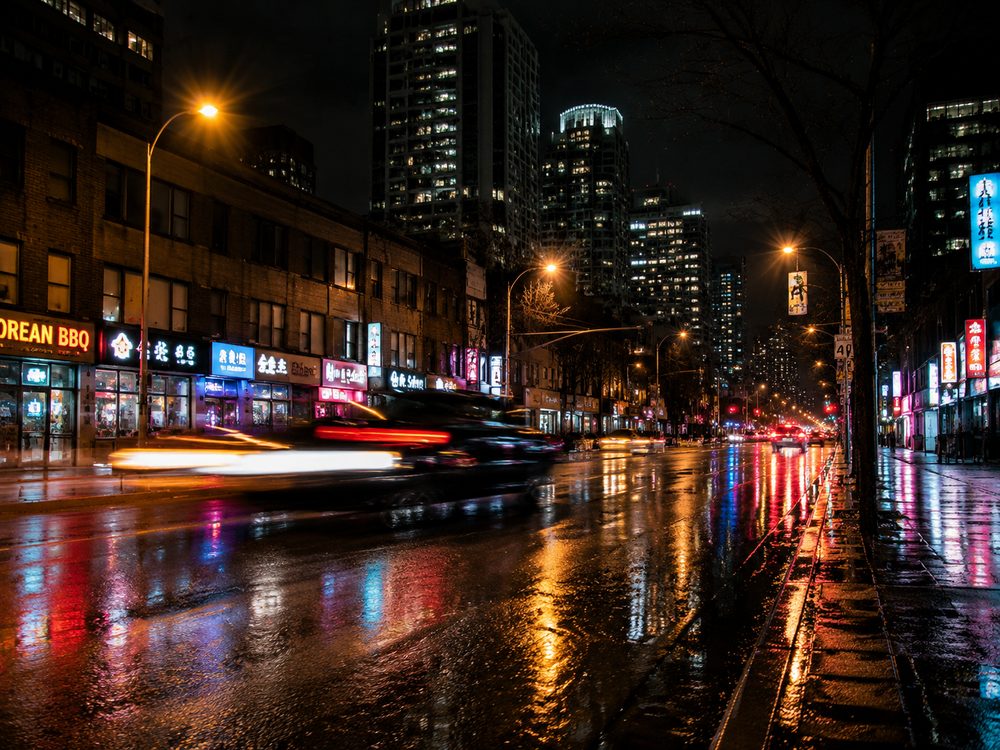
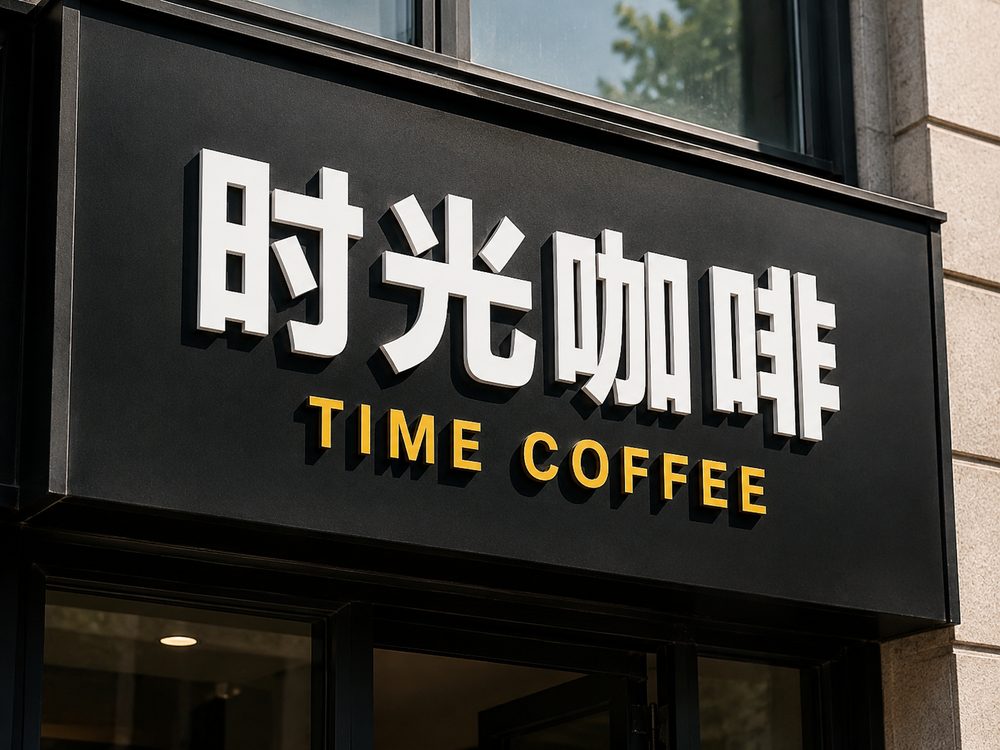
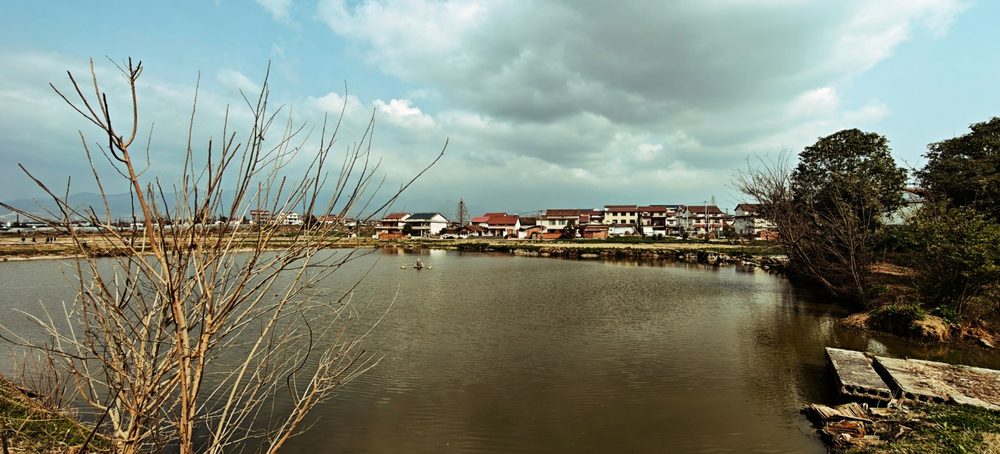
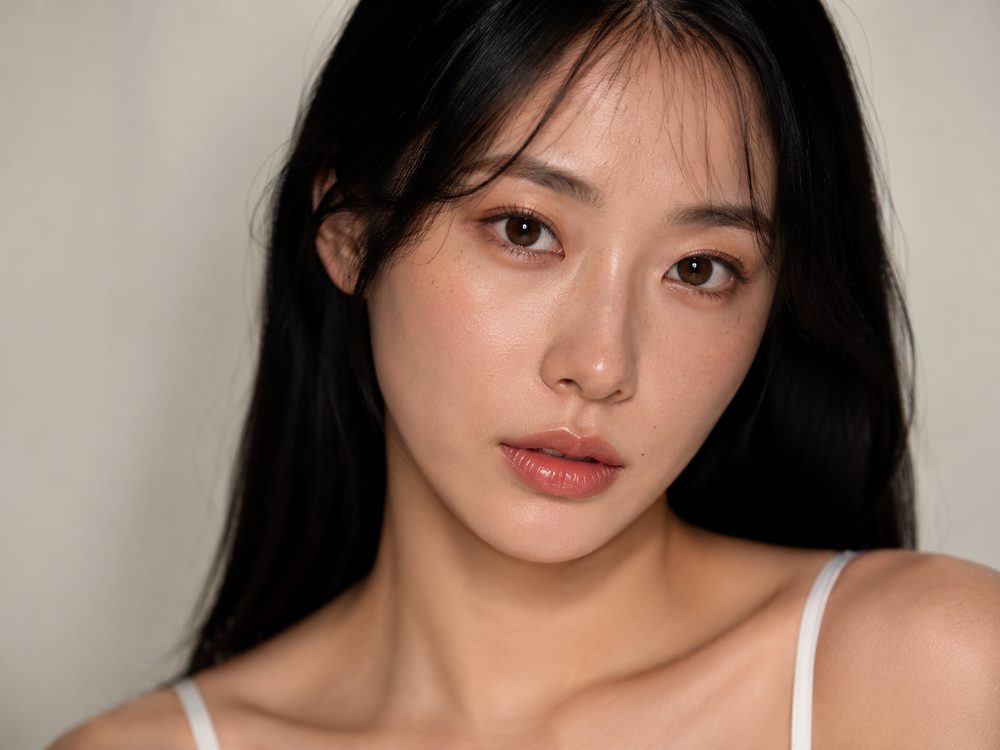
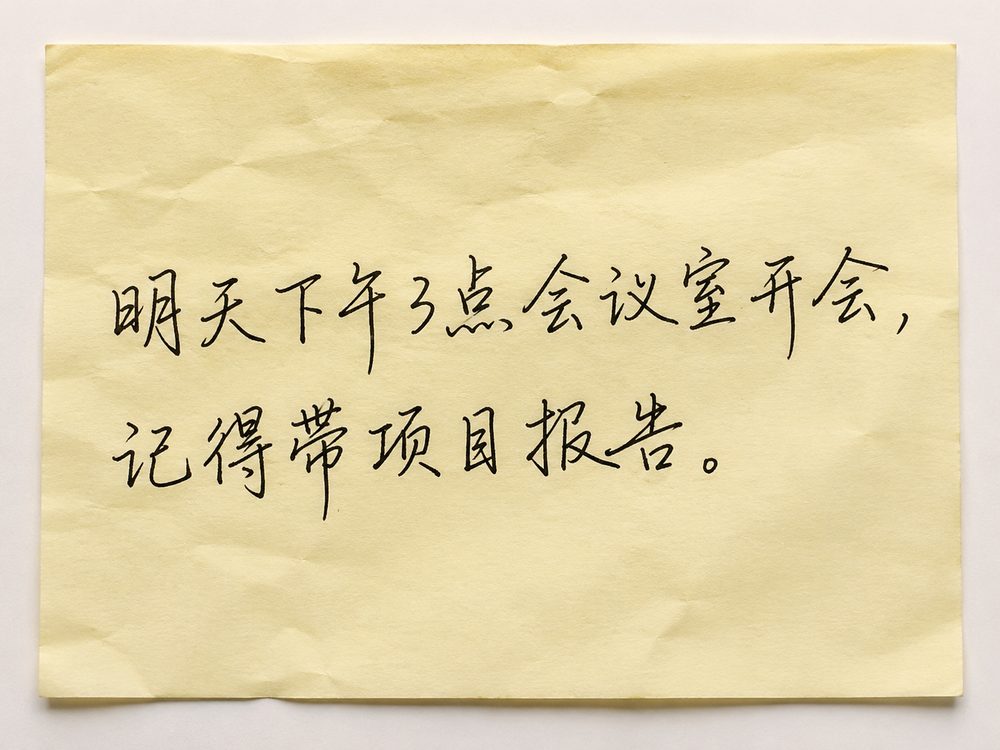
What's inside
- DataImages with per-pair text annotations
- StatsCategory counts, tag histogram, resolution distributions
- ProvenanceSource and construction method documented
- IntegritySHA-256 checksums for verification
Release record & integrity
| Version | 1.0.0 — 2026-10-06 |
| Archive | 297,379,369 bytes (298 MB) |
| SHA-256 | 42694f4ea3f722a2… |
| Annotation | Human-annotated, single annotator, dual-track (dense-tag 57 / structured bilingual 22) |
| Provenance | Field-collected photographs and controlled generation, manually screened and deduplicated |
| Public samples | 12 of 79 pairs published on this page |
Citing & licensing
The dataset page on the lab site carries the current license text and version history. If you build on it, tell us — we keep a running list of derived work.