Research
Published, checksummed, and honest about limits.
We release what we build — datasets with provenance, methods with limitations, and evaluation plans before results. This index only lists real artifacts; there are no filler entries.
Featured dataset
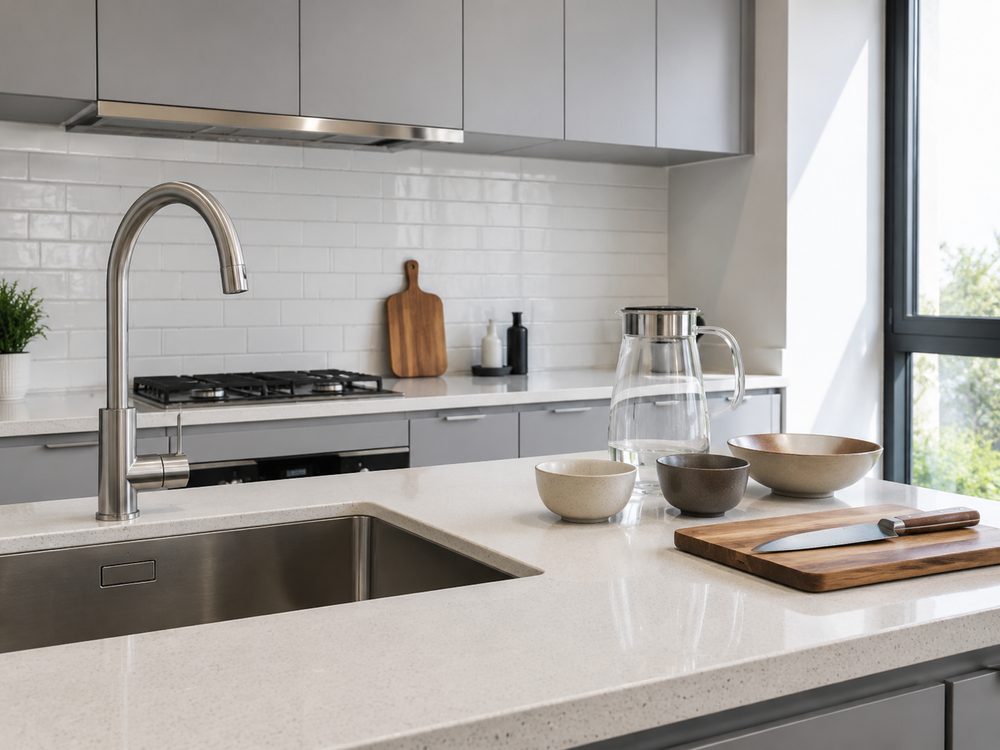
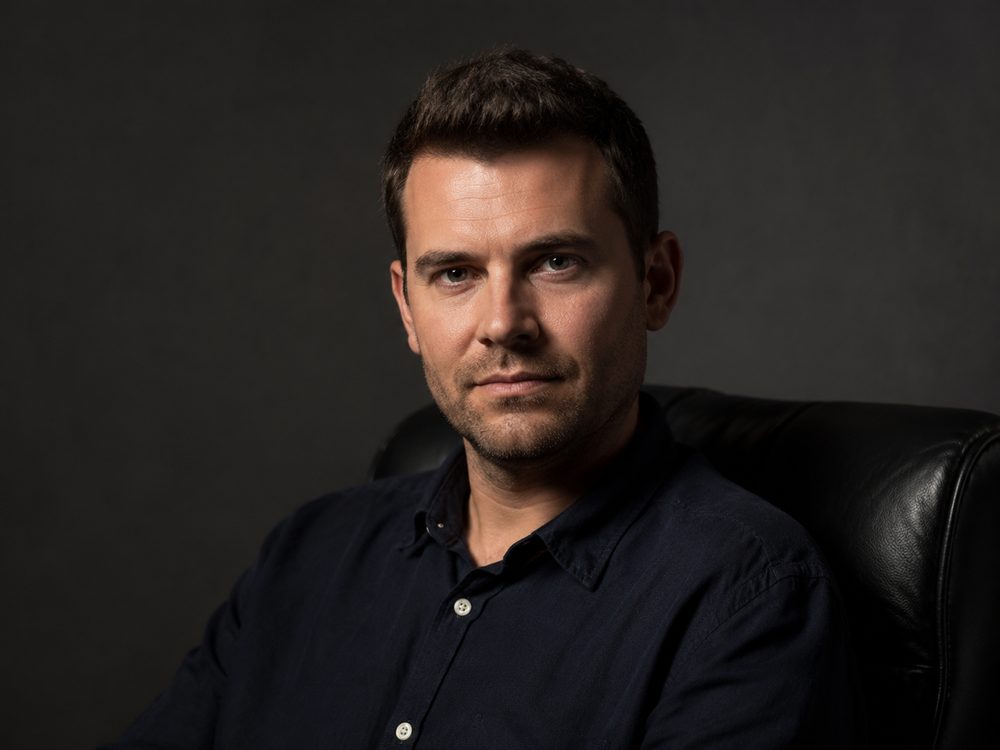
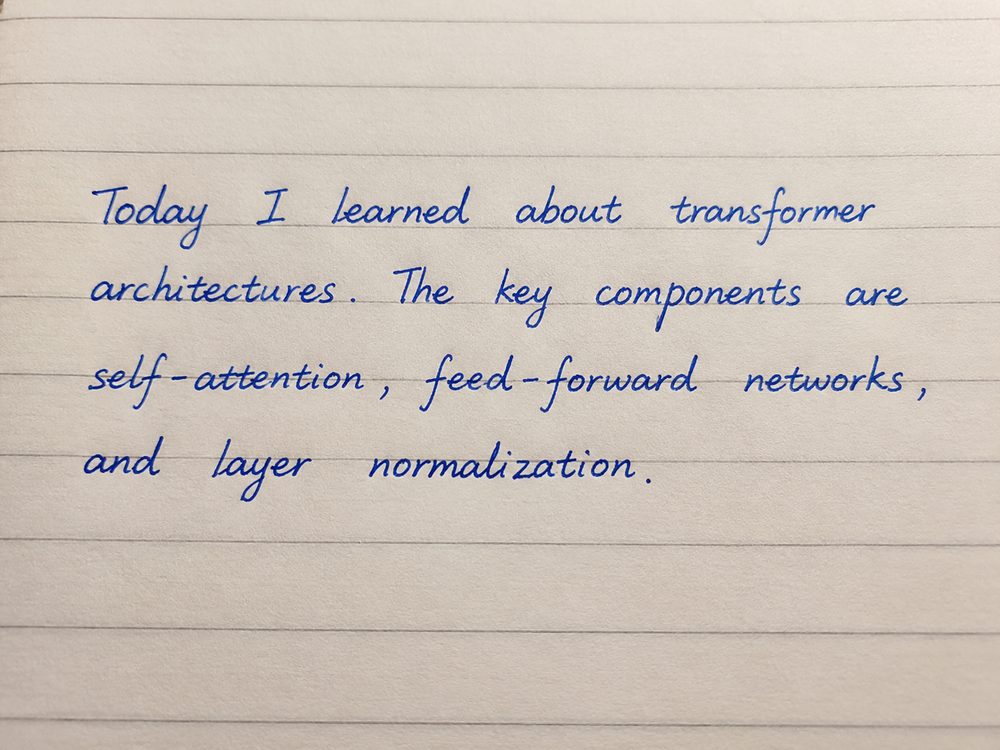
OevuAI Image Training Corpus v1.0.0
79 curated image–text pairs, 298 MB, dual-track annotation (dense-tag and structured bilingual), full category and resolution statistics, SHA-256 checksums for every file, and documented provenance.
Index
- 2026.10.06Dataset — Image Training Corpus v1.0.0
- 2026.10Plan — evaluation framework
- 2026.10Note — annotation & versioning methodology
The research log is also kept on the lab site: oevuai.com/lab.
From the dataset — real numbers, not renders
Category distribution (79 pairs)

Tags per image
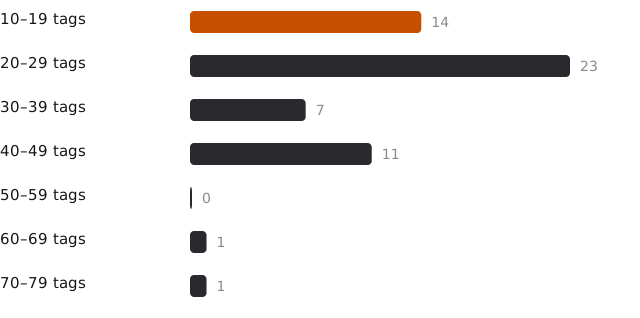
Release v1.0.0 · 2026-10-06 · archive 297,379,369 bytes · SHA-256 42694f4ea3f722a2… · annotated by a single annotator, Feb 2025 – May 2026.
Status
Datasets
One public release; more in preparation. Statistics and checksums ship with every version.
Evaluations
The framework is defined; first runs are in progress. We will publish results — including unflattering ones — when they exist.
Methodology
Dataset construction, annotation, versioning, limitations, and reproducibility are documented up front.